RART: Regional Anchor Routing
for Multi-Object Motion Transfer
1 Tianjin University2 Smart Creation Platform Department, Online Video BU, Tencent3 University of Auckland
Abstract
Compositional motion transfer requires a model to extract motions from multiple reference videos and apply each motion to a user-specified object in one target scene. Existing methods struggle to reliably assign different reference motions to the correct target objects, allowing a motion intended for one object to affect another. We present RART, a framework that unifies object-wise motion extraction, target-region anchoring, and frame-aligned injection into a frozen video Diffusion Transformer. For each reference, RART extracts temporally ordered features from the masked video and conditions them on the target first-frame mask to form mask-anchored motion tokens. Frame-aligned motion cross-attention allows each generated frame to read motion tokens at the corresponding time slots, composing all object motions in one denoising process. A motion-attention routing loss encourages each target region to attend to its own motion tokens and reduces interference between objects. RART handles novel reference–target combinations without per-video optimization, supporting accurate motion preservation and compositional generalization.
Method
Object-wise motion encoding, regional anchoring, and frame-aligned control.
01ExtractIsolate each reference motion with DisMo.
02Anchor & alignBind motion tokens to target regions and time.
03RouteDiscourage cross-object motion interference.
Qualitative Results
The target image defines the scene. Each reference supplies one object's motion.
Object-wise motion reassignment
Target image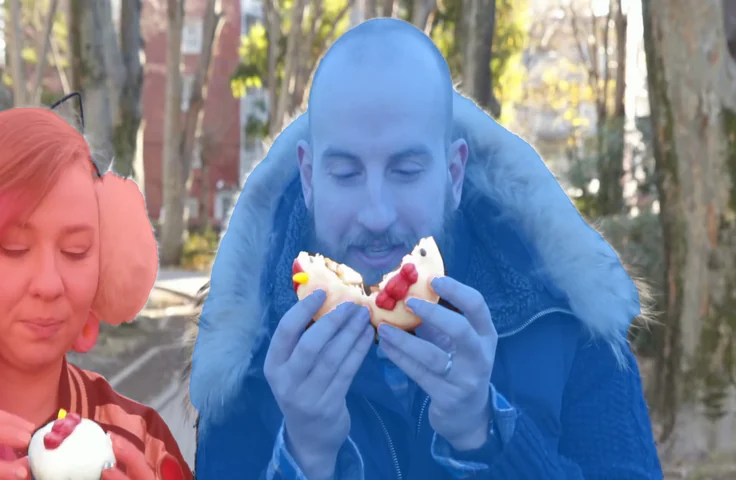
Human–animal motion composition
Target image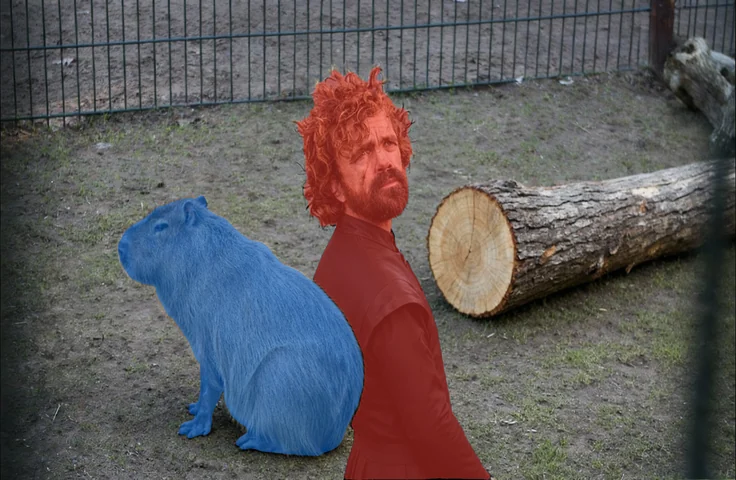
Qualitative Comparison
A shared target scene and motion references, compared across five methods.
See the paper for quantitative evaluation, implementation details, and additional analysis.
BibTeX